
Cutting Vendor Onboarding Cycle Time Without Risk
Vendor onboarding cycle time is rarely lost where teams think it is. The delay is almost never the approval step everyone watches; it is the idle days between steps, waiting on a document that was never requested, a workforce credential that lapsed, or a shipment that arrived before anyone was staged to receive it. Compressing the timeline is a sequencing problem, not a shortcut problem.
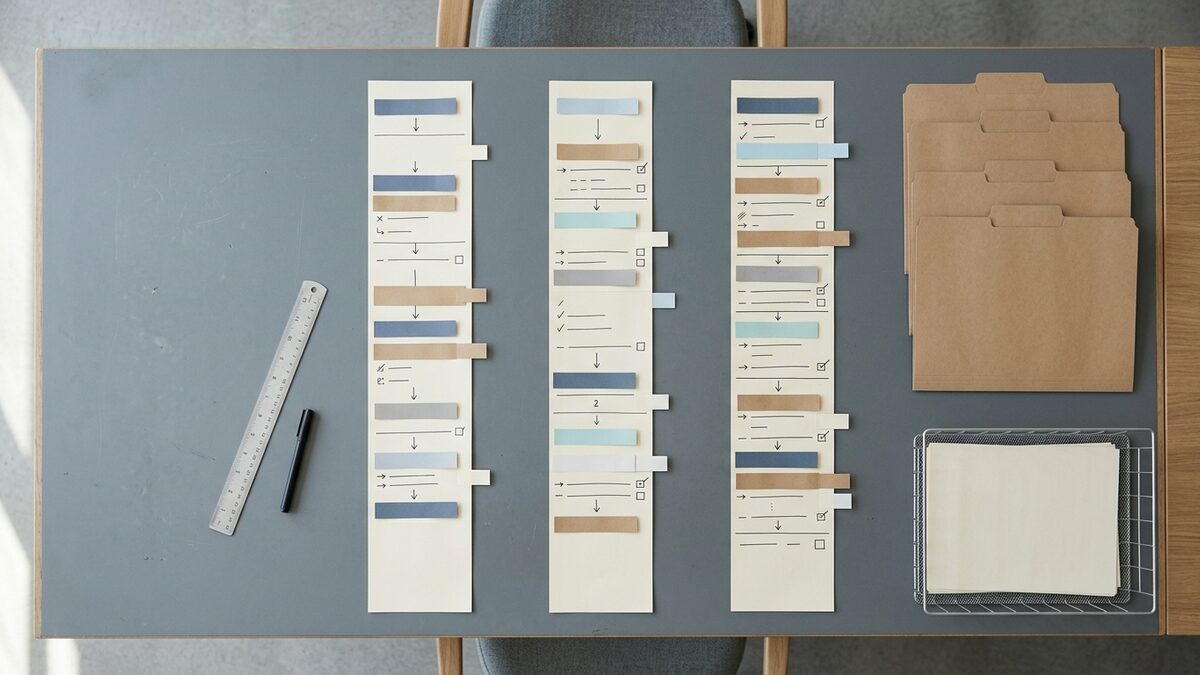
Start by separating cycle time into two categories: work time and wait time. Work time is the hours a task actually consumes when someone is doing it. Wait time is everything else, the queue depth between one completed step and the next one starting. In most onboarding pipelines, wait time is four to six times larger than work time. That ratio is the entire opportunity. Adding headcount to a fast step does nothing; removing the reason a file sits idle for three days does.
The three places cycle time consistently leaks are documentation gaps, workforce readiness, and logistics staging. Each fails in a predictable way, and each responds to a different fix. Treating them as one generic backlog is why most acceleration efforts stall.
Where the days actually disappear
Documentation gaps are the most common and the most avoidable. A vendor packet moves through review, gets to a compliance check, and stops because one attestation or one insurance certificate was never collected up front. The file then waits for a follow-up email, a vendor response, and a re-review. That single missing artifact can cost a full week of calendar time for what is ten minutes of work.
The fix is a completeness gate at intake rather than at review. Define the full document set before the packet enters the queue, and reject incomplete submissions immediately with a specific list of what is missing. This feels slower because it moves the friction earlier, but it removes the mid-pipeline stall that costs far more. A packet that enters review complete almost never bounces.
Workforce readiness is the second leak, and it hides well because it looks like a people problem rather than a process one. Credentials expire, background checks queue behind a vendor's own hiring cycle, and site-specific training gets scheduled only after everything else clears. Each of these has its own external clock you do not control. If you start them late, they become the critical path no matter how fast everything upstream ran.
The sequencing move here is to trigger anything with an external clock on day one, in parallel with document review, not after it. Background checks, credential verification, and mandatory training have long lead times and low failure rates. Starting them early costs almost nothing if the onboarding proceeds, and the rare wasted check is far cheaper than a two-week stall at the end.
Sequencing the work to compress the timeline
Logistics staging is the third leak and the one that produces the most visible failure: material or equipment arriving before anyone is ready to receive, inspect, or place it. When staging lags the paperwork, you get demurrage, storage fees, and a receiving team scrambling. When staging leads too far ahead, you carry inventory and risk that the vendor never clears review. The goal is to couple staging to a confidence signal, not to a calendar date.
A practical confidence signal is the completeness gate passing plus the external-clock items being in flight. At that point the probability of the vendor clearing is high enough to begin staging without meaningful waste. This is the core of compressing cycle time without skipping controls: you are not removing any check, you are running the independent ones concurrently and gating the expensive commitments on cheap early signals.
Build the pipeline as three parallel tracks that converge, rather than one serial line. Track one is documentation, front-loaded with a hard completeness gate. Track two is workforce readiness, triggered immediately on the external-clock items. Track three is logistics staging, held until the first two show green. The convergence point is your final approval, which now reviews a packet that is complete, credentialed, and staged, instead of initiating those activities.
Two metrics tell you whether the redesign is working. First, measure wait time as a percentage of total cycle time, and watch it fall as parallelization takes hold. Second, measure first-pass yield at the completeness gate, the share of packets that clear review without bouncing back for a missing artifact. A rising first-pass yield means your intake definition is correct and the mid-pipeline stalls are gone.
Resist the temptation to report only the headline number. Average cycle time can improve while a long tail of stuck vendors gets worse, because averages hide the outliers that generate escalations. Track the ninetieth percentile alongside the median. The percentile is what your worst-served vendors and your most frustrated internal stakeholders actually experience, and it is usually where the reputational cost lives.
None of this requires new tooling or added headcount. It requires deciding what must be true before a packet enters each queue, moving external-clock work to the front, and gating expensive commitments on cheap early signals. The controls stay intact; only the idle days between them disappear. That is where the cycle time was hiding the whole time.